AI Model API Marketplace
Browse image, video and face-swap model APIs. Try any model, then integrate it through one unified REST API.
147+ · AI Model API Marketplace · No subscription required: pay as you go. Top-up credits never expire; subscription credits expire after each grant period.
View all models: AI Generator
Image to Video
35
xAI Grok Imagine Video v1.5 Image to Video
Animate one input image with a text prompt into a 1-15 second video at 480p or 720p.
Vidu Q4 Preview Image to Video
Generate a 3–16 second video from a prompt and one image, with optional audio and prompt expansion. Supports 540p, 720p, 1080p, 2k and 4k.
vidu/q3/image-to-video-spicy
Vidu Q3 Image-to-Video Spicy generates unlimited high-quality videos from images with smooth animations and diverse motion, optimized for scalable content generation. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Vidu Q3 Image To Video
Vidu Q3 Image-to-Video turns text prompts into high-quality videos with exceptional visual fidelity and diverse motion. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.

MiniMax H3 Spicy Image to Video
Animate a first-frame image with optional prompt and last-frame guidance. Supports 480p, 540p, 768p and 1080p video, with durations from 3 to 15 seconds.
MiniMax H3 Image to Video
MiniMax H3 Image to Video animates a first-frame image into a coherent 2K video, with natural-language motion instructions and optional last-frame control for consistent motion, scene continuity, and cinematic video generation. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
ltx-2.5/image-to-video
LTX 2.5 Image-to-Video animates a first-frame image into high-fidelity synchronized audio-video content, with optional last-frame guidance and 720P / 1080P / 2K / 4K output for cinematic videos, social content, ads, and production workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
ai/ltx-2.3-spicy/image-to-video-lora
LTX 2.3 Spicy LoRA Image to Video API turns a reference image and prompt into expressive AI videos using selectable LoRA presets, optional LoRA strength overrides, duration, and resolution controls. Run fast REST inference on MaaS with no cold starts and affordable pricing.
Text to Image
30
z-image-spicy/text-to-image
Generate high-quality images from text with custom dimensions from 256 to 1536 pixels, intelligent prompt rewriting, and seed control for creative design and batch generation.
xAI Grok Imagine Image v2.0 Text to Image
xAI Grok Imagine Image V2.0 Text-to-Image generates high-quality images from text prompts, with configurable aspect ratio, resolution, and quality for creative visuals, social content, marketing assets, and production workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Qwen Image 3.0 Pro Text to Image
Qwen Image 3.0 Pro is a professional-grade text-to-image model with superior quality and advanced prompt understanding. Up to 2k. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
ai/prefect-pony-xl
Prefect Pony XL delivers high-quality anime-style image generation for character art and illustrations. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
OpenAI GPT Image 2 Text-to-Image
OpenAI's GPT Image 2 Text-to-Image generates high-quality images from natural-language prompts. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
OpenAI GPT Image 2 Edit
OpenAI's GPT Image 2 Edit enables image editing from natural-language instructions with one or more reference images. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
OpenAI GPT Image 2.5 Sunburst Text-to-Image
High-fidelity image generation for detailed compositions and demanding production work, with up to 4K output.
OpenAI GPT Image 2.5 Flare Text-to-Image
Fast, balanced image generation from natural-language prompts, with up to 4K output.
Image to Image
29
xAI Grok Imagine Image v2.0 Edit
xAI Grok Imagine Image V2.0 Edit transforms input images with text prompts, with configurable resolution and quality for precise image editing, visual refinements, creative variations, social content, marketing assets, and production workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
qwen-image-edit-spicy
Precisely edit images with text instructions. Add, remove, or modify visual elements, transfer styles, and replace backgrounds for photo retouching and visual design.
Qwen Image 3.0 Pro Edit | Fast Image Editing
Qwen Image 3.0 Pro Edit is a professional-grade image editing model with superior quality and advanced instruction understanding. Up to 2k. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
OpenAI GPT Image 2.5 Sunburst Edit
High-fidelity image editing for precise transformations using up to 16 reference images.
OpenAI GPT Image 2.5 Flare Edit
Fast, balanced image editing from natural-language instructions and up to 16 reference images.
Head Swap (Image)
Swap the head in a photo with the head from a reference image. Upload the target photo first, then the head reference.
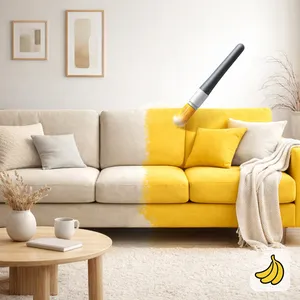
Nano Banana Image Edit
Fast & Affordable Editing. Intuitive object replacement and style transfer without manual masking.
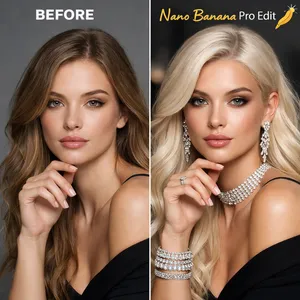
Nano Banana Pro Image Edit
4K Semantic Editing.Modifies existing images via natural language with context awareness and multilingual text editing.
Text to Video
14
xAI Grok Imagine Video v1.5 Text to Video
Generate 1-15 second videos from text prompts at 480p, 720p, or 1080p.
MiniMax H3 Text to Video
MiniMax H3 Text to Video generates coherent 2K videos from text prompts, with flexible 4-15 second duration and six selectable aspect ratios for cinematic scenes, creative videos, and production workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
ltx-2.5/text-to-video
LTX 2.5 Text-to-Video generates high-fidelity synchronized audio-video content from text prompts, with flexible duration and 720P / 1080P / 2K / 4K output for cinematic videos, social content, ads, and production workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Kling Omni Video O3 Standard Text-To-Video
Kling Omni Video O3 is Kuaishou's advanced unified multi-modal video model with MVL (Multi-modal Visual Language) technology. Text-to-Video mode generates cinematic videos from text prompts with subject consistency, natural physics simulation, and precise semantic understanding. Supports audio generation. Ready-to-use REST API, best performance, no coldstarts, affordable pricing.

Kling 3.0
Kling 3.0 delivers high-quality text-to-video generation with smooth motion, cinematic visuals, accurate prompt adherence, and native audio for ready-to-share clips. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
Kling V2.6 Text to Video API
Kling 2.6 delivers top-tier text-to-video generation with smooth motion, cinematic visuals, strong prompt adherence, and native audio for ready-to-share clips. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
Gemini Omni Flash Text to Video API
Gemini Omni Flash Text to Video creates short AI videos with synchronized audio from text prompts, combining visual generation and audio output for fast multimodal video creation. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Seedance 2.0 Mini Text to Video
Seedance 2.0 Mini Text to Video is ByteDance's faster, lower-cost text-to-video model for cinematic multi-shot videos. It generates narrative sequences from text prompts with AI camera control, consistent characters across scenes, 480P / 720P / 1080P / 4K output, 4-15s duration, and flexible aspect ratios. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Video to Video
9
VT Lip Sync
VT Lip Sync synchronizes mouth movements for a translated video by using the translated target video, translated audio, translated subtitle timing, and the original source video with its original subtitle timing.
Kling Omni Video O3
Kling Omni Video O3 Reference-to-Video generates creative videos using character, prop, or scene references from multiple viewpoints. Extracts subject features and creates new video content while maintaining identity consistency across frames. Supports audio generation. Ready-to-use REST API, best performance, no cold starts, affordable pricing.
Kling 3.0 Standard
Kling 3.0 Standard Motion Control transfers motion from reference videos to animate still images. Upload a character image and a motion clip (dance, action, gesture), and the model extracts the movement to generate smooth, realistic video. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
seedance-2-0 reference-to-video
The "Reference-to-Video" feature of Seedance 2.0 is the ultimate solution for visual stylistic unity. It precisely extracts artistic styles, lighting tones, or compositional intents from reference materials and seamlessly integrates them into newly generated videos, ensuring a highly consistent visual language for your creative series.
black-forest-labs/flux-3/video-upscale
From $0.79 for 1 second at default creativity=1; $0.55/second at creativity=0. Billed by input duration, rounded up to whole seconds. FLUX Video Upscale enhances MP4 videos with source-faithful or creative detail reconstruction, configurable 1.5x to 3x scaling, and improved visual clarity for video restoration, social content, ads, and production workflows. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
black-forest-labs/flux-3/video-extend-draft
FLUX 3 Video Extend Draft quickly continues a required input video into a draft clip with prompt-guided next-scene motion, optional synchronized audio, and flexible 5-20 second duration for rapid iteration.
black-forest-labs/flux-3/video-extend
FLUX 3 Video Extend continues input videos into new 5-20 second clips, using prompt guidance to control the next action, camera movement, visual style, motion continuity, and optional synchronized audio at 720P / 1080P output. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Reference to Video
8
xAI Grok Imagine Video v1.5 Reference to Video
Generate a 1-15 second video from a prompt and 1-7 reference images at 480p or 720p.
Vidu Q4 Preview Reference to Video
Generate a 3–16 second video from a prompt with optional references: up to 15 images and 3 audio clips. Supports aspect ratio selection, audio generation and 540p–4k resolution.
MiniMax H3 Reference to Video
MiniMax H3 Reference to Video generates coherent 2K videos from natural-language prompts and multimodal references, including images, videos, and audio, guiding subject consistency, motion, timing, visual style, and scene continuity. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Gemini Omni Flash Reference to Video API
Gemini Omni Flash Reference to Video creates short AI videos with synchronized audio from one or more reference images and a text prompt, preserving visual identity and following the provided references for guided multimodal video generation. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Seedance 2.0 Mini Reference to Video
Seedance 2.0 Mini Reference-to-Video is a high-speed, cost-effective video generation model developed by ByteDance, engineered specifically for creating multi-shot videos with a cinematic feel. By seamlessly combining reference images with text prompts, it generates highly narrative video segments. The model features advanced AI camera control and ensures robust character consistency across different scenes. It supports multiple output resolutions from 480P up to 4K, durations ranging from 4 to 15 seconds, and flexible aspect ratios. Complete with an out-of-the-box REST inference API, it delivers exceptional performance with zero cold starts, offering an affordable yet premium solution for professional video creation.
Seedance 2.5 Reference to Video
The "Reference-to-Video" feature of Seedance 2.5 is the ultimate solution for visual stylistic unity. It precisely extracts artistic styles, lighting tones, or compositional intents from reference materials and seamlessly integrates them into newly generated videos, ensuring a highly consistent visual language for your creative series.
Seedance 2.0 Fast reference-to-video
Seedance 2.0 Fast (Video-Edit) edits an input video from a natural-language prompt at a faster, cheaper tier. Built on ByteDance Seed's unified multimodal architecture, it preserves subject identity, composition, and motion while rewriting lighting, style, weather, environment, or specific elements as instructed. Ready-to-use REST API, best performance, no coldstarts, affordable pricing.
Wan 2.6 Flash Reference to Video
Generate a 2–10 second video using reference images or videos, with optional audio at 720P or 1080P.
Face Swap
5
namifusion Image/Video Face Swap
NamiFusion Video Face Swap Model Supports images and videos, easy single or multi-person face swapping. Compatible with multiple model_style options, can output realistic results or one-click beauty-enhanced versions — natural and great-looking!
换脸
NamiFusion Faceswap v5 is a high-speed, cost-effective model designed for large-scale, real-time workflows, delivering lifelike results with automatic skin tone matching and professional quality.
Image FaceSwap Pro
Image FaceSwap Pro supports single-face automatic detection and multi-face precise mapping with keypoint pairs.
namifusion Image Face Swap
NamiFusion Face Swap Model Easy single or multi-person face swapping. Compatible with multiple model_style options, can output realistic results or one-click beauty-enhanced versions — natural and great-looking!
FaceDetect
A face detection model used to detect facial information contained in input elements.
Character Swap
4Head Swap – Generate
Replace selected heads in the video with your reference images using Wan2.2-Animate. Keeps the original audio track.
Head Swap – Analyze
Detect and track heads in a video with SAM3. Returns a head list with preview images and a track manifest for the generate step.
Character Swap – Generate
Replace selected characters in the video with your reference images using Wan2.2-Animate. Keeps the original audio track.
Character Swap – Analyze
Detect and track every person in a video with SAM3. Returns a character list with preview images and a track manifest for the generate step.
Text to Speech
4
Eleven v3
The most expressive model. Supports 70+ languages. Requires more prompt engineering than our previous models.

Eleven Turbo v2.5
Our high quality, low latency model in 32 languages. Best for developer use cases where speed matters and you need non-English languages.

Eleven Multilingual v2
Our most life-like, emotionally rich mode in 29 languages. Best for voice overs, audiobooks, post-production, or any other content creation needs

Eleven Flash v2.5
Our ultra low latency model in 32 languages. Ideal for conversational use cases.
Avatar To Video
2
kwaivgi/kling-v2-ai-avatar-standard
Kling AI Avatar generates high-quality AI avatar videos for profiles, intros, and social content, delivering clean detail and cinematic motion with reliable prompt adherence. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
kwaivgi/kling-v2-ai-avatar-pro
Kling V2 AI Avatar Pro generates high-quality AI avatar videos with clean detail, stable motion, and strong identity consistency—ideal for profiles, intros, and social content. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Omni Reference
2
Wan 3.0 Omni Reference
Generates videos up to 30 seconds with native audio from multimodal references — images, video, audio, documents, and web pages. Reproduces characters, props, and spatial relationships from your references at pixel-level fidelity, with a first/last-frame mode for precise control.
Wan 3.0 Prime
Supports multimodal references including multiple images, video, and audio to generate videos with rich motion and synchronized audio-visual effects. Accurately preserves the appearance, motion characteristics, and visual style of referenced subjects, while supporting flexible combinations of references for versatile content creation and shot control.
For developers & creative teams
Choose how you build.
Compare NamiFusion with WaveSpeed AI and fal.ai across model discovery, task handling, pricing and agent access.
WaveSpeedalternative
Compare model discovery, prediction jobs, uploads, pricing visibility and MCP access for an application that generates media.
WaveSpeed vs NamiFusionfal.aialternative
Compare hosted media APIs, queue handling, model schemas, pricing tools and MCP, while keeping custom model deployment a separate requirement.
fal.ai vs NamiFusion